
On this page
Open Source Model
Overview
Vimoo 1.0 is an open-source video generation model built on the MMDiT architecture. It supports text-to-video (T2V) and image-to-video (I2V), using prompts or reference images to create videos with control over subjects, actions, scenes, and camera movement. Its lightweight variant, Vimoo 1.0 - Lite, supports both tasks in a single model designed for efficient inference. See Vimoo 1.0 for architecture, variants, and capabilities.
Open-Source Resources
Models are published in the Vimoo-1.0 Collection on Hugging Face.
| Model family | Hugging Face | Inference code | Integrations & Tools | Included models |
|---|---|---|---|---|
| Vimoo 1.0 |  Vimoo-1.0 |  Vimoo-1.0 | Diffusers | T2V, I2V |
| Vimoo-1.0-ComfyUI | ComfyUI-Vimoo | ComfyUI | T2V, I2V and their Distilled versions | |
| Vimoo 1.0 - Lite | Vimoo-1.0-Lite | Vimoo-1.0 | Diffusers | TI2V |
| Vimoo-1.0-Lite-ComfyUI | ComfyUI-Vimoo | ComfyUI | TI2V and its Distilled version | |
| Vimoo-1.0-Lite-MLX | Vimoo-1.0-MLX | MLX | TI2V Distilled on Apple Silicon |
T2V generates video from text; I2V adds a starting image. TI2V supports both tasks in one model. Lite is the lightweight model; Distilled versions use fewer sampling steps for faster generation.
Run Locally
Choose a framework for your device. For running locally, we recommend Distilled or Lite TI2V Distilled models.
Visual workflows on an NVIDIA GPU. Use T2V / I2V Distilled for more detail, or Lite TI2V Distilled for faster previews.
Works on an Apple Silicon Mac. Use the Lite TI2V model for text-to-video and image-to-video generation.
Generation Time by Device
For running locally, we recommend Vimoo 1.0 T2V Distilled / I2V Distilled, or Vimoo 1.0 - Lite TI2V Distilled.
Use the chart to compare the two text-to-video choices at 720p, 121 frames. It covers Vimoo-1.0 T2V Distilled and Vimoo-1.0-Lite TI2V Distilled; I2V timings are not shown. Times vary with generation settings and runtime environment.
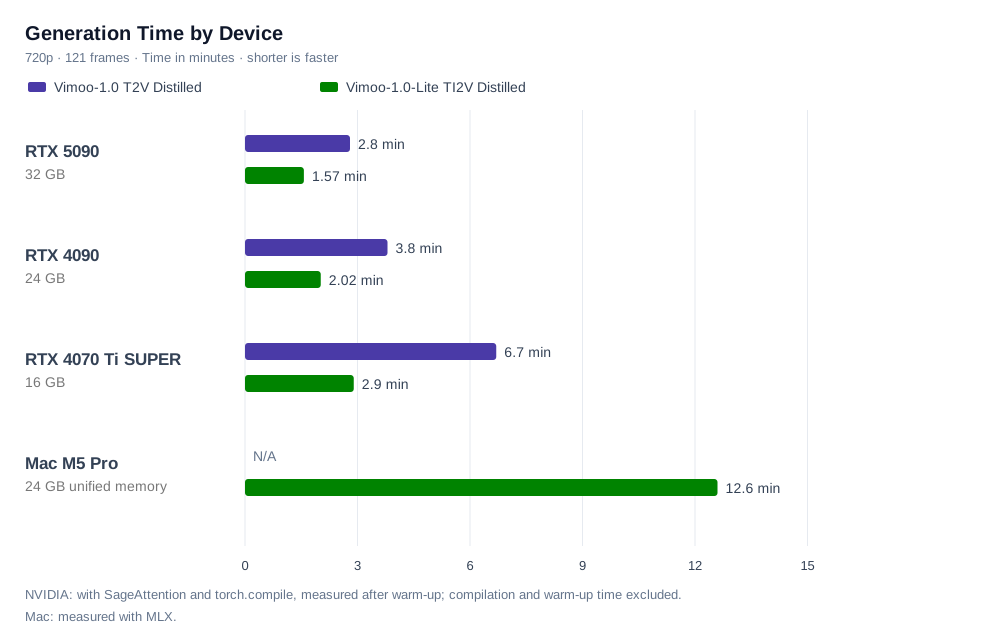
NVIDIA timings use SageAttention and torch.compile, measured after warm-up; compilation and warm-up time are excluded. Mac timings use MLX.